Stop AI Budget Overruns Autonomous AI Cost Governance
The only platform that makes optimal cost decisions in real time - without logging a single prompt.
DoCoreAI is an autonomous AI cost governance platform built for SaaS teams and AI-native companies shipping AI features
to customers.
Your customers' prompts are their data — never stored. DoCoreAI's
trained model governs your LLM costs autonomously,
in real time.
Runs alongside your application — never in the request path.
No gateway. No added latency. No prompt logging.
Proxy-based observability forces a choice:
log everything (compliance risk) or see nothing (budget risk).
Autonomous AI Cost Governance eliminates the trade-off.
$ pip install docoreai
Works out of the box with
Control AI Spend Across Every Team, Client & Environment
Allocate budgets across teams, clients, applications, and environments.
DoCoreAI predicts usage patterns and automatically paces AI spend to prevent budget overruns before they happen.
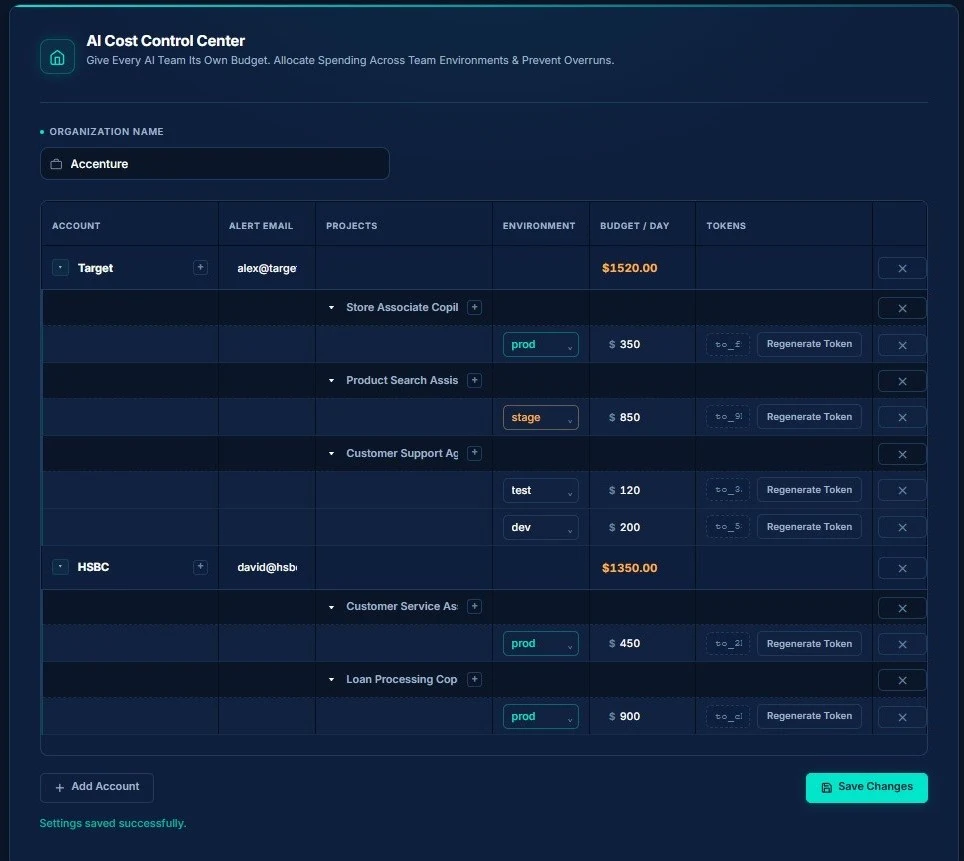
Set daily budgets per account and environment — DoCoreAI allocates spend across teams, prevents overruns, and governs every AI call autonomously.
Most AI Teams Can Protect Privacy Or Control Costs
— Not Both.
Your team ships an AI feature. Usage grows. Then one of two things happens — and neither option ends well.
You log everything
Prompts, responses, full request bodies. Now your compliance team is blocking the rollout.
- Legal wants a data retention policy immediately
- Security flags it as a liability
- Compliance team rejects the entire rollout
- The AI pilot stalls before it even starts
- Customer PII is sitting in your logs
You skip logging entirely
No compliance risk — but now you're completely flying blind on costs and performance.
- Costs spike overnight with zero warning
- Budget exhausted by Tuesday morning
- Service unavailable for 14 hours
- No audit trail, no governance
- No way to explain the bill to leadership
"Why did our AI spend jump from $1K to $47K last month?"
"Which team's AI workload needs a chargeback policy?"
"Did customer PII leak through that API call?"
"Why was our AI service down for 10 hours yesterday?"
Silent Token Waste
Default max_tokens
is set to 2,000+ as a safety net. Most responses need a fraction of that.
You pay for the ceiling — every single request.
No Native Guardrails
No LLM provider gives you budget pacing, spend prediction, or automatic intervention. You either overspend or build all of that yourself.
AI Projects Stalling
8% of enterprises report bill shock from AI costs. 45% went 50%+ over budget. Projects get canceled not because AI failed—but because costs were completely ungoverned.
Enterprise AI teams have visibility tools, privacy tools, and budget spreadsheets — but no AI Cost Governance.
DoCoreAI bridges this gap. Scroll down to see how.
DoCoreAI runs alongside your app —
Your AI costs. Governed
automatically
It instruments every LLM call your application makes — costs tracked, budgets enforced, anomalies caught. All within the same Python environment. No imports. No proxies. No changes to your existing code. DoCoreAI is designed to fail open: if instrumentation cannot be applied, it logs the issue, falls back safely, and allows your application and LLM calls to continue uninterrupted. No imports. No proxies. No wrappers. No changes to your existing code. DoCoreAI listens before and after each LLM call, extracts cost and token metadata locally, and applies governance, budget, and pacing decisions autonomously. Your app calls the LLM directly, unchanged. Only metadata reaches the cloud — prompts never leave your network.
Groq / Gemini SDK
Groq · Gemini · Bedrock
(same process)
-SQLIte
Dashboard · Alerts
every call
needed per request
& Auto-Retrain
accuracy continuously
if ≥5% better
DoCoreAI never sits in your call path. It monkey-patches the LLM SDK locally — listening before and after each call in the same Python process. Your app calls the LLM directly, unchanged. Only cost and token metadata is sent to the cloud. Prompts never leave your network. Ever.
Security teams can verify exactly what DoCoreAI stores — direct access to the local metadata database available on request. Request security review →
Metadata captured per call:
timestamp · model name · token count (input/output) ·
estimated cost · latency · governance decision applied.
Never captured:
prompt text · response content · user identifiers ·
any application data.
Data residency:
Enterprise residency requirements —
contact us
. Regional options on roadmap Q4 2026.
DoCoreAI is the first Autonomous AI Cost Governance platform — built on three architectural principles that make it possible.
Privacy-First Architecture
Your customers' prompts flow through your product. DoCoreAI ensures
they never leave it.
Ship AI features your customers can trust — full observability,
zero data retention liability on your side.
- Zero prompt or response logging
- Metadata-only telemetry, is non-sensitive by design — cost and token counts carry zero confidential information
- Local-side instrumentation, nothing sensitive leaves your network
- PII detection at the edge before any API call
- Prompts never leave your network
- Complete audit trails without compliance risk
No-Gateway Architecture
No proxy sits between your product and the LLM. Your AI features stay fast and reliable — DoCoreAI instruments alongside your app without touching your call path or slowing your customers down.
- Your LLM calls go direct — no proxy in the path
- No request-path network dependencies
- Installs via a simple pip package
- No added latency — DoCoreAI runs in the same process, not in the network path. Zero milliseconds added to your LLM response time.
- Fails open by design — if DoCoreAI cannot instrument a call, your application continues normally. LLM requests are never blocked.
- Integrates with zero code changes
AI Cost Governance
When your AI feature goes viral, your LLM costs shouldn't spiral. DoCoreAI predicts, paces, and controls spend autonomously — so usage spikes don't become billing emergencies.
- Predictive token budgeting
- Dynamic, rolling 24-hour budget pacing
- Local drift monitoring & model auto-retraining
- Automated spend control
- Per-account and per-environment cost attribution — built for showback
- Defeats AI bill shock at the application tier
- Long-term cost audit trail — full governance history retained
DoCoreAI vs. Proxy-Based Observability
| Capability | Proxy-Based Observability | DoCoreAI |
|---|---|---|
| Prompt storage | ~ Often stored | ✓ Never stored |
| AI cost governance | ✕ Limited visibility only | ✓ Built-in |
| Per-team attribution | ✕Not available | ✓ Built-in |
| Autonomous budget control | ✕ Not available | ✓ Built-in |
| Budget pacing | ✕ Not available | ✓ Built-in |
| AI cost prediction | ✕ Reactive reporting | ✓ Predictive controls |
| No gateway required | ✕ Proxy or request-path dependency | ✓ Runs beside your app |
| Added latency | ✕ High risk (via proxies) | ✓ No added latency |
| PII protection | ~ Limited | ✓ Edge-based detection |
| Multi-provider support | ~ Varies | ✓ All major providers |
| Zero code changes | ✕ Integration work required | ✓ Auto-patches SDKs |
Three commands. Production-ready.
Install in the same Python environment as your application. Python 3.12+ required. Works on Windows, macOS, and Linux.
Generate your free org token at docoreai.com and run the one-time setup. Takes under two minutes.
DoCoreAI automatically intercepts all LLM SDK calls. No changes to your application code required. Ever.
DoCoreAI Doesn't Just Observe AI Spend — It Governs It
Already using Datadog, CloudHealth, or Apptio? DoCoreAI operates at the AI application layer — governing the spend your existing FinOps stack cannot see.
Most AI monitoring tools show what happened. DoCoreAI continuously analyzes usage patterns, predicts future spend, and automatically applies budget controls before costs become overruns.
AI WORKLOAD COVERAGE
Why DoCoreAI Is Different..?
Native dashboards show you what happened
after the bill arrives.
DoCoreAI predicts and prevents
before the call is made.
Built for every team
running AI in production
From SaaS platforms to regulated enterprises — DoCoreAI extends your FinOps practice into AI workloads, with per-team attribution, spend prediction, and autonomous budget controls your existing tools can't provide.
Budget exhausted by noon. Service down for 12 hours.
A marketing email triggers a customer surge at 9 AM. Without pacing, the entire daily budget is gone by 11 AM — leaving your AI service unavailable for the remaining 13 hours. Support tickets flood in. The engineering team scrambles.
- Budget exhausted by 11 AM
- Service down 13 hours
- 50+ support tickets
- Emergency engineering response
- No warning before it happened
- Spike detected, throttling engaged
- Service runs full 24 hours
- Same daily budget — no increase
- Zero engineering intervention
- Automatic — no human action needed
Black Friday volume 5× normal. Budget planned for average days.
Holiday traffic runs 5× your normal daily volume. Without seasonal awareness, aggressive throttling kicks in during your most critical sales window — degrading customer experience exactly when it matters most.
- Throttling during peak sales hours
- Degraded AI responses on Black Friday
- No seasonal pattern awareness
- Budget exhausted mid-campaign
- Lost conversions at peak moment
- Peak-aware strategy recognises anomaly
- Allows temporary over-pace during sale
- Compensates automatically in off-hours
- Spend stays within monthly envelope
- Full quality during critical window
Need full AI observability. Cannot log a single prompt.
Healthcare and financial services teams need complete cost visibility and governance. But traditional observability tools log prompt content — making them a compliance and legal liability before they've even been deployed.
- APM tools require prompt logging
- Compliance team blocks deployment
- Legal flags data retention risk
- AI pilot stalls indefinitely
- Flying blind on costs and performance
- Zero prompt storage — ever
- Metadata-only telemetry architecture
- PII detection blocks leaks at edge
- Full cost visibility, zero compliance risk
- 7-year audit trail — no sensitive content
AI-Powered SaaS
Keep AI features running 24/7 without budget surprises. Automatic pacing handles traffic spikes invisibly.
Financial Services
Full AI observability with zero prompt retention. SOX-compliant audit trails without compliance risk.
Healthcare
HIPAA-friendly architecture. PII detection at the edge. Patient data never leaves your network.
Retail & E-Commerce
Seasonal pattern learning keeps AI performant during peak campaigns without blowing the monthly budget.
Developer Tools
Drop-in SDK integration. Per-team cost attribution. Stop guessing which feature is burning your AI budget.
Enterprise & Government
Multi-tenant governance, RBAC, and SSO support. Built for organizations where security is non-negotiable.
Autonomous AI Cost Governance:
17 months of research.
Real signals. Real momentum.
Built on waste patterns observed across 20+ enterprise AI engagements. Every feature exists because a real team hit a real wall.
From idea to production-ready platform
Identified the privacy vs. visibility gap across 20+ enterprise AI engagements. Started building DoCoreAI to solve it at the infrastructure level.
✓ CompleteCore observability SDK published. LLM cost, token, and latency tracking across OpenAI, Anthropic, and Groq.
✓ Live on PyPIBudget pacing, soft limits, and PII detection engine added. Multi-provider support expanded to include Google Gemini and AWS Bedrock.
✓ Live on PyPIPredictive budget model, A/B testing, drift detection, and auto-retraining shipped. Closed source from v2.0.
✓ Current versionFull cloud dashboard with real-time spend curves, per-team attribution, and anomaly detection. Enterprise pilot program opens.
BetaRBAC, SSO/SAML, and multi-tenant governance for enterprise deployments. SOC2 certification targeted.
⏳ RoadmapLive on PyPI
Install today with
pip install docoreai
.
Full source available at
pypi.org/project/docoreai
.
Python 3.12+ required.
Architecture Waitlist Open
Multi-agent orchestration and RAG support are on the roadmap. Reserve your spot now — get notified the moment your architecture pattern goes live.
Problem validated at scale
The same privacy vs. visibility gap was observed in every single one of 20+ enterprise AI engagements. This is not a niche problem — it is the default state of production AI.
"Before DoCoreAI, I advised 20+ enterprise AI teams on production readiness and governance. The same gap appeared every time — teams could build impressive AI features but couldn't answer basic questions like 'Why did costs spike 400%?' or 'Did customer PII leak through that API call?' AI initiatives died not from technical failure but from lack of visibility and control. DoCoreAI is my answer to that problem."
Explore DoCoreAI
See how it works, what it costs, and how to measure the impact — track tokens across your large language models (LLM), monitor spend, and prove ROI for the team that signs off on the budget.
The dashboard — and increasingly the autopilot — for your AI spend.
Read more → ⚙️Cost analytics, prompt health, and autonomous budget pacing — all without storing your prompts.
See features → 📊Explore a sample dashboard — cost, prompt health, and ROI, built from sample data.
Open the demo → 🩺A practical framework for measuring and improving prompt quality.
Read the guide → 💸Six prompt-tuning techniques that reliably cut spend, plus a savings calculator.
Cut costs → 📈Translate AI usage into cost, productivity, and ROI leadership can act on.
See the dashboard →
Running LLMs in production?
Let's solve it together.
We are actively seeking 3–5 enterprise design partners for no-cost pilots with white-glove founder support. If your team is wrestling with AI cost visibility or compliance constraints — this is built for you.
- Full platform access at zero cost
- Direct founder support and configuration help
- Early access to enterprise features
- Input into the product roadmap
- Co-development of your specific use case
- Priority access when Pro tier launches
- Honest feedback on what works and what doesn't
- Real usage data to improve prediction models
- Willingness to co-develop your use case with us
- A case study if outcomes are strong
Prefer email? Reach Saji directly at [email protected]
Design Partner
Full platform access, white-glove founder support, and direct input into the roadmap. Zero cost. 3–5 spots available.
Book a Call ↗Install & Try Free
Three commands. No code changes. Start tracking your LLM costs and tokens in under 15 minutes.
pip install docoreai ↗Read the Docs
Full configuration reference, architecture guide, and integration walkthroughs at docoreai.com/docs.
View Documentation →
Reserve your spot.
We'll notify you first.
Leave your details and we'll reach out the moment your architecture goes live — before general availability.
You're on the list.
We'll reach out to the moment your architecture goes live — you'll be first in line.
